Ellis Jung · 18 September 2026
Examining Log File Patterns to Optimize Crawl Budget Allocation in Dynamic Web Environments
Web administrators and search engine optimization specialists examine server log files to identify how automated agents allocate resources across sites that update frequently, and this process reveals patterns that influence indexing efficiency in environments where content changes in real time. Dynamic web environments generate continuous streams of data through user interactions, API calls, and automated updates, which means that crawl budget allocation becomes a matter of directing limited resources toward pages that deliver the highest value for search visibility.
Core Concepts of Crawl Budget Management
Crawl budget represents the number of pages a search engine bot processes during a given visit, and it depends on factors such as server response times, site architecture, and the frequency of content modifications. Researchers at institutions studying web-scale data collection have documented that sites with high update rates require precise allocation to prevent bots from wasting capacity on duplicate or low-priority resources. Log files record each request with timestamps, user agents, status codes, and referrers, which provides the raw material for mapping these interactions into actionable patterns.
Analysts parse these records to distinguish between productive crawls and inefficient loops, and they often discover that certain URL structures trigger repeated visits while others remain overlooked. Data from industry reports indicate that improper allocation can delay indexation of newly published material by days or weeks in fast-moving sites.
Identifying Recurring Patterns in Log Data
Common patterns emerge when teams review logs over extended periods, including clusters of requests around specific directories, spikes during content refresh cycles, and repeated hits on parameter-heavy URLs that produce identical output. In dynamic settings, these clusters frequently align with database-driven sections where inventory or user-generated content shifts hourly, and log analysis tools segment the data to isolate bot behavior from human traffic. Observers note that September 2026 brought renewed attention to these techniques after several research papers highlighted improved detection methods for bot signatures in high-velocity environments.
One study revealed that sites employing parameter filtering reduced redundant crawls by measurable percentages, while another tracked how seasonal traffic surges altered budget distribution across regional server clusters. Those who've studied this know that combining log data with server performance metrics uncovers bottlenecks where slow responses cause bots to deprioritize entire sections.
Techniques for Pattern Analysis and Optimization
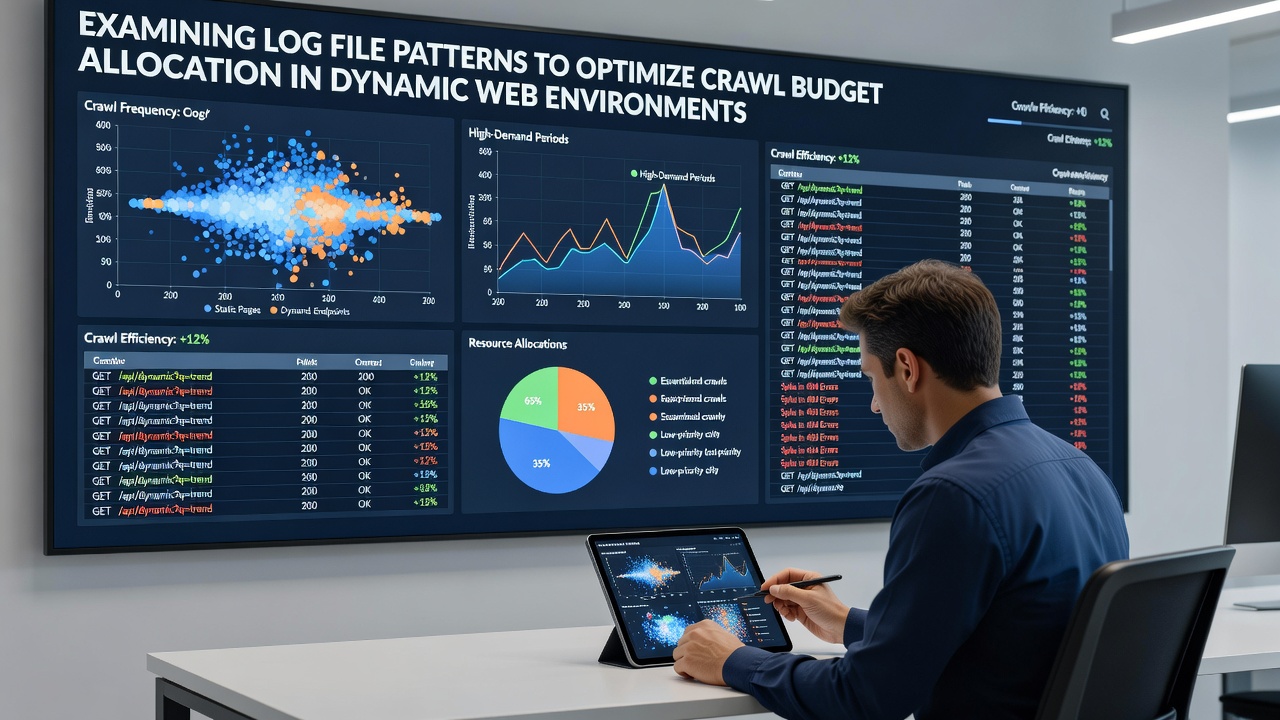
Teams apply regular expressions and statistical models to log entries so they can group similar requests and calculate visit frequencies per URL segment, and this approach allows them to create rules that guide bots toward high-value pages through internal linking adjustments or robots.txt refinements. Active monitoring systems flag anomalies such as sudden increases in 404 responses or concentrated activity on staging directories, which often indicate configuration drift that wastes budget. According to documentation from Google's developer resources, controlling duplicate content paths represents a primary lever for preserving allocation in complex sites.
Further refinement comes from cross-referencing logs with sitemap submissions and change-frequency signals, and analysts have observed that dynamic sites benefit when these signals match actual update patterns rather than default settings. Research from academic sources such as papers published through Carnegie Mellon University's data mining group demonstrates how machine learning classifiers trained on historical logs predict future crawl demand with increasing accuracy. These methods help administrators shift resources away from low-impact areas without manual intervention on every change.
Case Examples from Production Environments
Take one large e-commerce platform that processed millions of product updates daily and discovered through log review that bots spent disproportionate time on filtered category views, and after implementing canonical tags and crawl-delay adjustments the team redirected capacity toward newly added inventory pages. Another organization managing a news aggregation service found that API-generated content endpoints received inconsistent attention until log segmentation revealed timing mismatches with publication schedules, after which they synchronized update signals with bot visit windows.
These examples illustrate how pattern recognition translates into concrete allocation improvements, and they show that the same principles apply across different content velocities and technical stacks. Observers note consistent gains when analysis incorporates both server-side and client-rendered elements in modern JavaScript-heavy applications.
Conclusion
Log file examination supplies the evidence needed to align crawl budget with the realities of dynamic content production, and organizations that maintain disciplined analysis routines achieve more timely indexation and reduced resource waste. Continued evolution in detection techniques, particularly those emerging around September 2026, supports finer control over how automated agents navigate complex sites. The data collected in server logs remains the foundation for these optimizations, and its systematic review continues to inform practical adjustments in web environments where change is constant.